SalsaNext+: A Multimodal-Based Point Cloud Semantic Segmentation With Range and RGB Images
Fabio Sánchez-García, Santiago Montiel-Marín, Miguel Antunes-García, Rodrigo Gutiérrez-Moreno, Ángel Llamazares Llamazares, Luis M. Bergasa
IEEE Access
Abstract
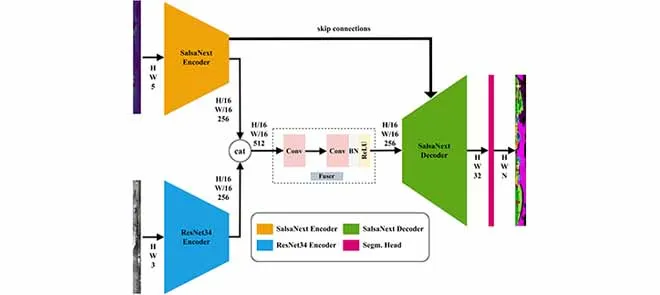
Advances in sensor fusion techniques are redefining the landscape of 3D point cloud semantic segmentation, particularly for autonomous driving applications. We propose an enhanced approach that leverages the complementary strengths of LiDAR and multi-camera systems. This study introduces two extensions to the state-of-the-art SalsaNext model based only in LiDAR: SalsaNext+RGB, which integrates RGB data into range-view (RV) images, and SalsaNext+PANO, incorporating panoramic images built from multi-camera setups. The proposed methods are evaluated using the SemanticKITTI and Panoptic nuScenes datasets, showing notable improvements in segmentation accuracy. Results indicate that RGB fusion boosts performance with minimal latency, while panoramic integration offers additional gains at the expense of higher computational load. Comparative analyses highlight significant mIoU gains, demonstrating the potential of multimodal sensor fusion for intricate driving scene understanding.
Citation
@article{sanchez2025salsanext,
  title={SalsaNext+: A Multimodal-Based Point Cloud Semantic Segmentation With Range and RGB Images},
  author={Sánchez-García, Fabio and Montiel-Marín, Santiago and Antunes-García, Miguel and Gutiérrez-Moreno, Rodrigo and Llamazares Llamazares, Ángel and Bergasa, Luis M.},
  journal={IEEE Access},
  volume={13},
  pages={64133--64147},
  year={2025},
  publisher={IEEE},
  doi={10.1109/ACCESS.2025.3559580}
}